What was broken
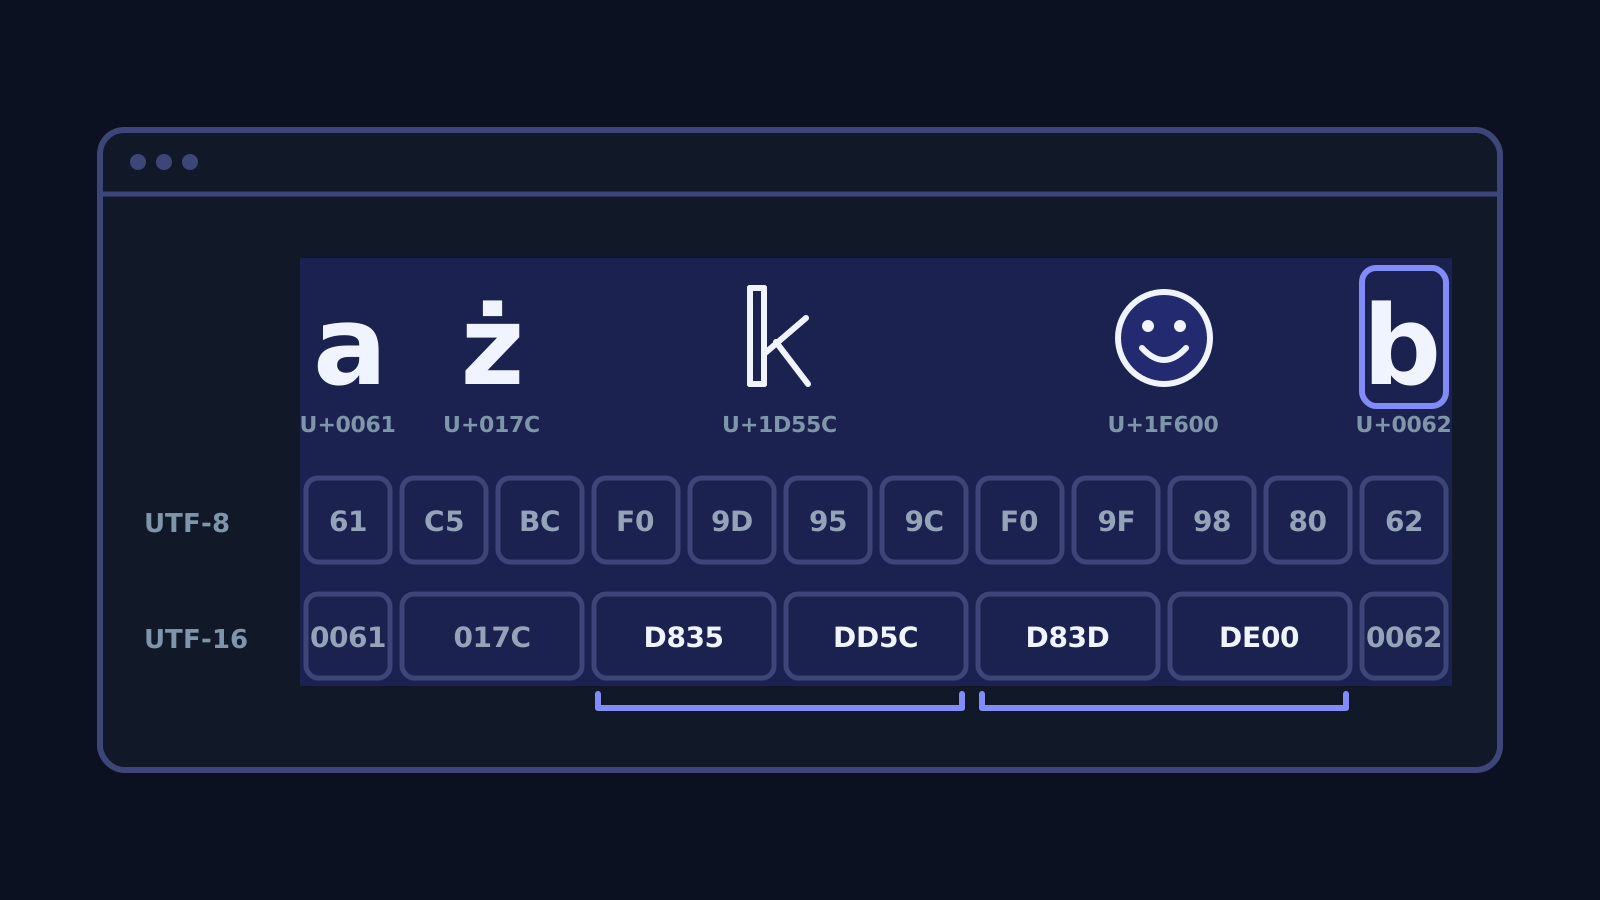
The vscode-neovim extension runs a real Neovim underneath VS Code. Neovim counts columns in UTF-8 bytes and VS Code in UTF-16 units, so every selection has to be converted. Characters outside the Basic Multilingual Plane, such as most emoji or 𝕜 (U+1D55C), take two UTF-16 units, a surrogate pair.
In visual mode the end of a selection is inclusive, while in VS Code it is exclusive, so the code added one UTF-16 unit to the end column. With a two-unit character the selection ended in the middle of the pair (issue #2535).
What we changed
Instead of adding one UTF-16 unit, the code first moves the end of the selection past the whole character in bytes, and only then converts the column to UTF-16:
byte_after_char uses vim.str_utf_end to find the last byte of the character and clamps at the end of the line.
How we tested it
We added three integration tests: a selection over one character outside the BMP, over two of them in a row, and over a mix of ordinary multi-byte characters and characters outside the BMP. We could not run the integration suite locally and said so in the pull request, so the project's CI was its first run.
The result
The change was merged on 23 September 2026. Selections in text with emoji and mathematical characters now cover whole characters.